

Relational Databases vs. Graph Databases: What’s the Difference?
Key Takeaways
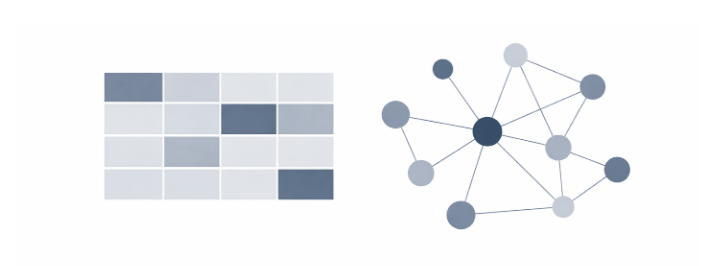
- Relational databases organize data as tables – they are built around things and their attributes.
- Graph databases organize data as nodes and edges – they are built around connections between things.
- The real question is not which database is faster. It is about the requirements. It is whether your questions are about records or about connections.
- Relational databases struggle when you need to follow long chains of relationships across many tables.
- Graph databases are not optimised for large-scale aggregations across flat data.
What is a relational database?
Relational databases have dominated enterprise data management for over 50 years for three main reasons: consistency, standardisation, and maturity. Data remains reliable, SQL is widely understood, and the tooling is well established.
At their core, relational databases store data in tables, organised into rows and columns, similar to a very powerful spreadsheet. Each row is a record such as a customer, an order, or a transaction. Each column is an attribute of that record such as a name, a date, or an amount.
Tables link to each other using keys. For example, to determine which orders belong to which customer, the customer ID is stored in the orders table. At query time, the database follows that reference and combines the tables. This is called a JOIN, and it is the core mechanism that makes relational databases work. As questions become more complex, the number of JOINs increases. This can lead to what is often called join explosion, where the number of intermediate combinations grows rapidly and queries become harder to optimise and slower to run.
SQL databases generally fall into two categories. Transactional databases such as MySQL, PostgreSQL, Oracle, and SQL Server are designed to record individual events quickly while maintaining consistency. Analytical databases, often called data warehouses, such as Snowflake, Redshift, and BigQuery, are designed to run large queries across historical data. Both use tables and SQL.
Relational databases are designed to answer questions about things. How many customers placed orders last month? What is the current stock level? What did this account spend in Q3? These questions have a known shape. You design the table structure to answer them before the data arrives. Where they can struggle is when the question shifts from records to relationships.
How Ally Built a Modern Fraud Intelligence Platform
Learn how Ally applied graph analytics and contextual investigation tools to uncover complex fraud networks and strengthen fraud prevention.
Read Case Study
What is a graph database?
A graph database stores data as nodes and edges. A node represents a thing – a person, an account, a company, a device. An edge represents a connection between two things – owns, transferred money to, is employed by, called. Both nodes and edges can carry properties (a name, a date, an amount).
The critical difference from a relational database is where the relationship lives. In a relational database, the relationship is inferred at query time by joining tables. In a graph database, the relationship is stored directly alongside the data – it exists as a first-class object, not a pointer to be resolved later.
This means following a chain of connections does not degrade in the same way as join-heavy queries. In a relational database, every additional hop in the chain requires another JOIN – and the cost grows with the complexity of the query. In a graph database, following a relationship is a direct traversal, like tracing a line on a map. The database does not need to resolve the relationship at query time; it follows it directly.
Graph databases are relationship-first. They are designed to answer questions about connections: who is connected to whom, by how many steps, through what path, and with what pattern. These are often questions you could not have fully anticipated when you designed the data model.
How do they compare?
| Relational Database | Graph Database | Knowledge Graph | |
|---|---|---|---|
| How data is stored | Rows and columns in tables | Nodes (things) and edges (connections between things) | Nodes, edges, and semantic meaning – entities are typed and relationships are defined in a model |
| Mental model | A spreadsheet with linked sheets | A map of everything and how it connects | A map where every connection has a defined meaning |
| Optimized for | Structured records with known, stable relationships | Data where the connections between things matter as much as the things themselves | Understanding what data means, not just what it contains |
| Starts to struggle when… | You need to follow chains of relationships across many tables | You need to aggregate or count across huge flat datasets | Source data is inconsistent, poorly labelled, or not mapped to the model |
| Best real-world fit | Running the same questions week after week on structured records. If you already know what you’re going to ask, this is your tool. | Finding connections you didn’t know were there. If the question involves following links across people, accounts, or events, this is where relational starts to break. | Understanding what your data means, not just what it contains. Right for complex enterprise environments where different systems use different labels for the same thing. |
| Typical tools | MySQL, PostgreSQL, Oracle, SQL Server | Neo4j, Amazon Neptune | DataWalk, Stardog, Cambridge Semantics |
| Query language | e.g. SQL | e.g. Cypher, Gremlin, GQL | e.g. SPARQL, Cypher |
How does each database actually work?
Think of a relational database as a set of filing cabinets, each labelled by type – one for customers, one for orders, one for products. Every piece of information goes into the correct cabinet and the correct drawer. To find out which products a customer ordered, you pull the customer drawer, find their ID, go to the orders cabinet, find all orders with that ID, then go to the products cabinet to find what those orders contained. It works well. It is organized. But every question requires visiting multiple cabinets in sequence.
A graph database works differently. Instead of separate cabinets, every piece of information sits in a web of direct connections. The customer node is physically linked to their order nodes, which are physically linked to the product nodes. To answer the same question, you start at the customer and follow the connections – no cabinet-switching, no cross-referencing. The more hops the question requires, the bigger the advantage.
In a well-built graph database, following a relationship is like following a signpost: it is far less sensitive to overall data volume. The relationship does not need to be calculated at query time. It is already there.
One common workaround in relational databases is to collapse multiple tables into one large table to reduce the number of JOINs a query has to perform. It can make certain queries faster, but it means storing the same data in multiple places, and it makes the structure harder to change later. Graph databases do not need this workaround. The relationships are already part of the model.
What type of database should I use?
The clearest signal is the shape of your questions. If your questions are predictable and involve counting, filtering, or summarising records (how many, how much, which ones) a relational database is probably the right fit. Banks, payroll systems, inventory management, and e-commerce platforms all run on relational databases for good reason. The data is structured, the questions are known, and the consistency guarantees that SQL databases provide are essential.
If your questions involve following connections (who is linked to whom, what path exists between two entities, what patterns appear across a network) a graph database becomes the better fit. Fraud detection is the clearest example. A fraud analyst does not just want to know how much money moved through an account. They want to know whether that account shares a phone number with another account that shares a device with three more accounts that all transferred money to the same destination within 48 hours. That is a multi-hop relationship query. A relational database can answer it, but the SQL becomes unwieldy and slow. A graph database answers it naturally.
Other situations where a graph database makes more sense: mapping the connections in a supply chain, finding hidden relationships between people in an investigation, building a recommendation engine, understanding how diseases spread through a population, or detecting anomalies in a network of devices. What these share is that the answer lives not in the data itself but in the pattern of connections between data points.
Which database is faster depends entirely on the nature of the problem you are trying to solve. A graph database asked to sum ten million transaction records will be outperformed by a relational database. A relational database asked to find all entities connected within three degrees of separation across fifty million records will be outperformed by a graph database.
| Requirement / Question Shape | Relational Database (SQL) | Graph Database |
|---|---|---|
| Aggregations (how many, how much, totals) | Strong – optimised for set-based operations | Weak – not primary strength |
| Filtering known attributes (which records match X) | Strong – indexed queries perform well | Moderate – possible but not optimal |
| Predictable, repeatable queries | Strong – schema and queries are stable | Moderate – works but overkill |
| Strict consistency | Strong – mature and reliable | Moderate – varies by implementation |
| Data with fixed structure | Strong – schema-defined | Moderate – flexible but not required |
| Multi-hop relationship queries (paths, connections) | Weak – requires complex JOINs | Strong – native traversal |
| Unknown or evolving questions | Weak – requires query redesign | Strong – flexible exploration |
| Pattern detection across networks | Weak – difficult to express efficiently | Strong – core capability |
| Entity-centric analysis (who is connected to whom) | Weak – indirect via joins | Strong – first-class model |
| Real-time traversal (low-latency path queries) | Weak – degrades with depth | Strong – consistent traversal performance |
| Schema flexibility / evolving relationships | Moderate – changes are costly | Strong – relationships are flexible |
What about platforms like Snowflake and Databricks?
Snowflake and Databricks are cloud data platforms built in the relational and analytical tradition – fast, scalable, and designed to make large datasets accessible to business users without requiring a team of database engineers. Both have invested heavily in blurring the line between OLTP (transactional) and OLAP (analytical) workloads, historically managed by separate systems.
What these platforms do not change is the fundamental challenge of highly connected data. Making a relational system faster or more flexible does not alter the JOIN cost at the heart of multi-hop relationship queries. Graph is not a faster relational database. It is a different answer to a different class of problem – one where the connection is the data, not a pointer to it.
Vendors are converging on a single-platform model: vendors are positioning their platforms as the central place for both storage and analysis. Whether any single platform can genuinely handle transactional, analytical, and relationship-first queries equally well is still an open question. The trade-offs between transactional, analytical, and relationship-heavy workloads remain unresolved.
Learn more
- How DataWalk Compares to Graph Databases, Knowledge Graphs, and Link Analysis Tools – A direct comparison of DataWalk’s hybrid architecture against standalone graph databases and knowledge graph products
- Knowledge Graph Software – How DataWalk’s unified knowledge graph integrates graph, relational, and AI capabilities into a single analytical platform
- Entity Resolution Software – How DataWalk identifies and links matching records across datasets to create unified entity views without coding
- Introduction to Knowledge Graphs – A Transformative Approach to Working with Data – A whitepaper on how knowledge graphs differ from relational databases and why they are better suited for complex, interconnected enterprise data
- Cracking a $5.7M Fraud in 120 Minutes – A case study showing how graph-based investigation resolved a complex fraud case that four weeks of conventional analysis could not
How DataWalk AI is Transforming Investigative and Intelligence Analytics
Download the eBookFAQ
What are OLTP and OLAP?
OLTP stands for Online Transaction Processing – the kind of database work that records individual events as they happen: a payment, a login, an order placed. These operations are fast, small, and happen in high volume. OLAP stands for Online Analytical Processing – the kind of work that runs large queries across historical data: total revenue by region for the last five years, average order value by customer segment. Relational databases were originally designed for OLTP. Analytical data warehouses (like Snowflake) were designed for OLAP. The two workloads have different performance requirements, which is why they were traditionally managed separately.
Is a graph database the same as a knowledge graph?
In a directed graph, edges have a defined direction, a financial transfer from account A to account B is different from a transfer in the opposite direction. In an undirected graph, edges simply indicate that a relationship exists without specifying which way it runs; a shared address is the same relationship regardless of which entity you start from.
Do graph databases replace relational databases?
No. Most organisations that adopt graph databases keep their relational databases running alongside them. Relational databases remain the right tool for transactional workloads – recording orders, processing payments, managing accounts. Graph databases are added where relationship-heavy queries are required. The two technologies are more often complementary than competitive.
Is SQL used in graph databases?
No. SQL is the standard query language for relational databases. Graph databases use different query languages – Cypher and Gremlin are the most widely used, and GQL (Graph Query Language) is an ISO standard for graph queries published in April 2024 – the first new ISO database language standard since SQL itself in 1987.
Why haven’t graph databases replaced relational databases if they are better at relationships?
Because most data problems are not primarily relationship problems. The majority of enterprise data workloads involve structured records, known schemas, and predictable queries – exactly what relational databases were designed for. Graph databases have genuine advantages for connected data problems, but those problems represent a subset of what organizations need to do with their data. Relational databases also benefit from five decades of optimization, tooling, and SQL fluency across the developer workforce – advantages that do not disappear because a newer technology handles one class of problem better.
What is contextual analytics?
Contextual analytics is the practice of analyzing data together with its surrounding business meaning, entities, relationships, history, permissions, provenance, and operational context. It helps organizations understand not only what happened, but what it is connected to, why it matters, and what action should follow.
What is data contextualization?
Data contextualization is the process of turning raw or fragmented data into meaningful, connected, reusable context. It connects records to real-world entities, relationships, definitions, permissions, provenance, and history so teams can work from a shared understanding rather than isolated tables, files, or extracts.
What is Persistent Context?
Persistent Context is reusable, governed context that survives beyond a single project. It allows new sources, workflows, investigations, applications, models, and AI initiatives to extend an existing intelligence model instead of rebuilding context from scratch.
How does DataWalk create Persistent Context?
DataWalk maps data to a flexible ontology and maintains entities, relationships, permissions, provenance, and analytical structure in one extensible intelligence model. New sources and use cases extend this model rather than creating disconnected context in separate marts, graphs, or knowledge bases.
Is DataWalk a knowledge graph?
DataWalk uses ontology and graph concepts, but it is broader than a standalone knowledge graph. It operationalizes connected context across entity resolution, search, graph analytics, investigation, scoring, workflows, applications, APIs, MCP, and AI access on one governed context layer.
Does DataWalk replace a data lake or warehouse?
No. DataWalk does not replace existing data lakes, warehouses, or source systems. It connects data from those environments and turns it into reusable context for analytics, investigations, workflows, applications, decisioning, and AI agents.
Why does Persistent Context matter for AI?
AI needs more than clean data. It needs governed context such as resolved entities, explicit relationships, permissions, provenance, definitions, and controlled analytical functions. Without this, AI systems often rely on isolated files or extracts, which leads to weak explainability, poor governance, and inconsistent answers. DataWalk provides a persistent context layer that AI agents and models can consume through APIs, MCP, and analytical functions.
DataWalk Platform
See DataWalk in action
Request a personalised live demo and discover how DataWalk connects the dots across your data.